Uber Redesigns Go-Based Translation Cache to Reduce Memory Footprint by Over 90%
According to InfoQ, Uber overhauled its Go-based translation cache, achieving a reduction in initial memory usage of over 90% while maintaining p99 cache miss latency under one millisecond.
-
The Tech TL;DR:
- Uber rebuilt its Go translation cache to drop initial memory overhead by over 90%.
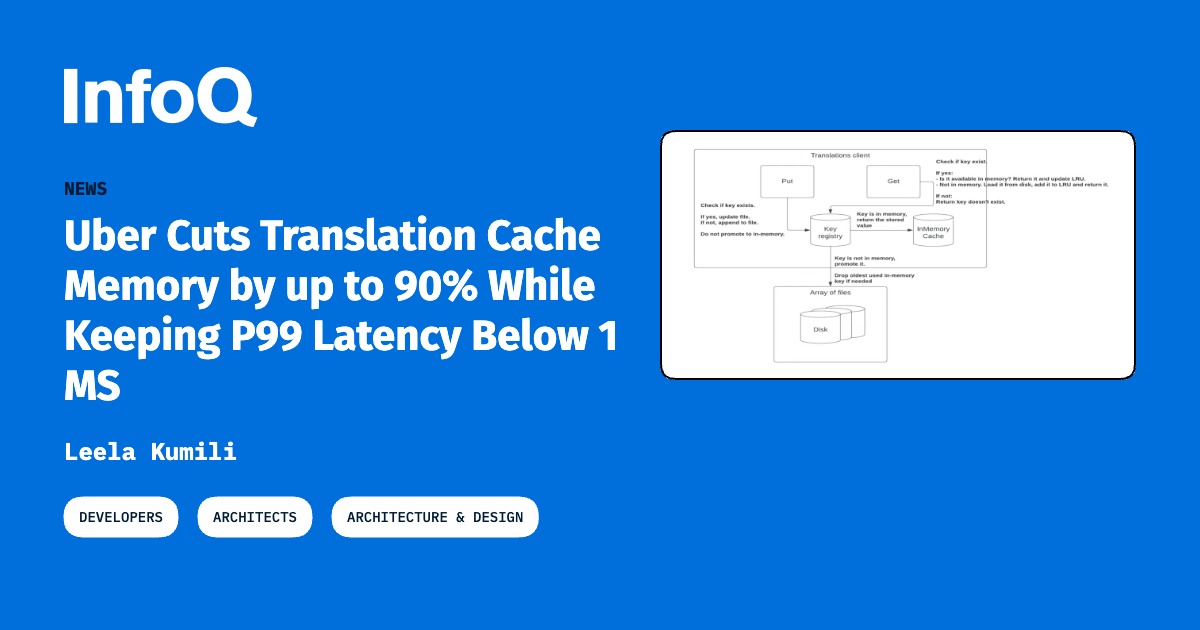
- A hybrid architecture stores keys and frequent values in memory while moving remaining data to disk.
- The updated system serves millions of translations per second with a hit rate exceeding 99.9%.
Garbage collection consumed more than 20% of CPU utilization in some services, with translations accounting for approximately 70% of allocated objects, according to InfoQ. Uber Engineering said that at Uber’s scale, even small inefficiencies in memory management can add up.
To perform the initial optimization, the team swapped Go’s sync.Map for a standard map[string]string that utilizes an RWMutex for protection. The workload was predominantly read-heavy, with infrequent updates and no individual deletions.
While translation datasets might hold between two and three million keys, individual services generally only required access to a small portion of them. Cache refreshes introduced another issue because the service built a replacement cache in the background before atomically swapping it with the existing one.
Both copies occupied memory simultaneously, causing some services to run out of memory during refreshes. The team adopted a hybrid storage design that preserves the existing Get() and Put() API.
| Metric | Previous Implementation | Hybrid Redesign |
|---|---|---|
| Memory Consumption (Dataset A) | ~800 MB | ~40 MB (metadata) |
| Total Memory Range | Higher peak usage | 80 MB – 120 MB |
| Memory Consumption (Dataset B) | ~2.7 GB | 750 MB |
The system is implemented using 256 shards, with each possessing a unique disk file, in-memory entries, and read-write mutex. To lower metadata overhead, the team utilizes six-byte hash-based keys, employing a fallback to the original key format whenever collisions occur.
A time-based global least recently used policy manages in-memory entries. To prevent a cold cache after a swap, the system uses access history during refreshes to preload any translations that were accessed within the previous 15 minutes.
As noted in an example by InfoQ, a translation dataset that previously occupied about 800 MB of memory required only 40 MB for metadata following the redesign. With an in-memory entry limit set at 50,000, memory usage typically fluctuated between 80 MB and 120 MB.
In another workload mentioned, more than four million entries existed, with roughly 30,000 loaded into memory, and the cache hit rate stayed above 99.9%. The p99 latency for disk-backed cache misses stayed below 100 microseconds, and memory usage decreased from approximately 2.7 GB to 750 MB.
Uber’s experience highlights the cost implications of in-memory caching at scale. The team advises keeping object references to a minimum to lower GC overhead and tracking the access frequency of cached values.
Founded in 2009 and launched publicly in San Francisco in 2011, Uber operates in approximately 70 countries and 15,000 cities worldwide. The company coordinates an average of 42 million trips and delivery orders per day, totaling 72 billion since inception. This massive scale underpins the engineering challenges described in the article, where translation datasets containing millions of keys must be served with high throughput and sub-millisecond latency.
Always consult with certified IT and cybersecurity professionals before altering enterprise networks or handling sensitive data.