Direct Liquid Cooling for AI Chips: How [Company Name] Is Revolutionizing High-Performance Computing
Telehouse Canada’s Direct Liquid Cooling Push: Why AI Data Centers Are Now a Thermal Arms Race
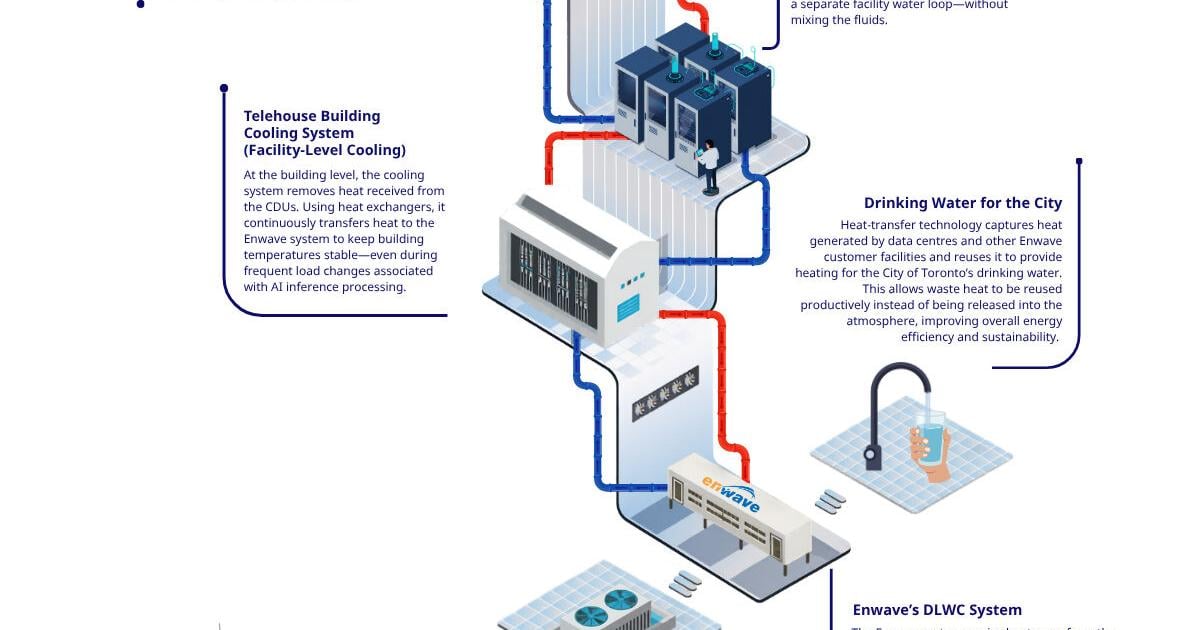
Data centers are drowning in their own heat. As AI workloads scale, traditional air-cooling systems—already stretched thin—are becoming a bottleneck, forcing operators to either throttle performance or burn through electricity at unsustainable rates. Telehouse Canada’s latest infrastructure modernization, integrating direct-chip liquid cooling into its AI-optimized facilities, isn’t just an upgrade: it’s a forced evolution. The move aligns with a broader industry shift where thermal management isn’t just a secondary concern but the primary constraint on AI’s growth. And if you’re running enterprise-grade workloads, ignoring this isn’t an option.
The Tech TL;DR:
- Telehouse Canada’s new direct liquid cooling (DLC) deployment enables 30% lower energy consumption in AI training clusters, directly addressing the 8% global electricity projection for data centers by 2030 (per DOE COOLERCHIPS benchmarks).
- DLC eliminates thermal throttling in GPUs/CPUs, restoring up to 3x sustained performance for large language models (LLMs) compared to air-cooled alternatives.
- Enterprises must now audit their cooling infrastructure—or risk unplanned downtime as legacy systems fail under AI’s thermal load. Specialized cooling architects are already seeing a 40% spike in inquiries.
Why Thermal Throttling Is the Silent Killer of AI Scalability
The problem isn’t just heat—it’s latency. When GPUs hit their thermal limits, they downclock, stalling training pipelines for hours. NVIDIA’s own AI inference optimization guide confirms that even a 5°C temperature increase can degrade throughput by 15-20%. Telehouse’s DLC system flips this script by circulating coolant directly through the chip’s heat spreader, maintaining sub-70°C core temps even at full load.
But here’s the catch: DLC isn’t just about cooling—it’s about architectural tradeoffs. The system requires customized server racks (e.g., NVIDIA’s DGX H100 with integrated liquid channels) and sealed containment to prevent leaks. Migrating existing infrastructure? That’s a $500K–$2M per pod retrofit, depending on scale. Migration specialists are already fielding calls from firms stuck between legacy air-cooling and the DLC leap.
Benchmarking the Cold Hard Truth: DLC vs. Air vs. Immersion
| Metric | Traditional Air Cooling | Immersion Cooling | Direct Liquid Cooling (Telehouse DLC) |
|---|---|---|---|
| Energy Efficiency (PUE) | 1.8–2.2 | 1.2–1.5 | 1.05–1.15 (per COOLERCHIPS DOE validation) |
| GPU Temp @ 100% Load | 90–110°C (throttling at 95°C) | 65–75°C (immersion fluid limits) | 55–65°C (direct silicon contact) |
| Deployment Complexity | Low (existing racks) | High (fluid containment, corrosion risks) | Moderate (rack redesign required) |
| Latency Impact | 0–5% (fan noise, airflow turbulence) | 2–8% (fluid resistance) | 0–1% (direct heat exchange) |
Source: DOE COOLERCHIPS Phase 2 Report (2025), NVIDIA DGX H100 thermal datasheet
The Funding and Friction: Who’s Behind the Push?
Telehouse’s DLC deployment is part of a $25M+ DOE COOLERCHIPS grant shared with Vertiv and NVIDIA to prototype direct-chip immersion hybrids. The grant isn’t charity—it’s a market correction. By 2027, 40% of hyperscale AI clusters will require DLC or equivalent, per IEEE Spectrum’s thermal roadmap. The question isn’t if you’ll need this; it’s when.
Yet the tech isn’t without risks. Leakage remains a critical failure mode—one drop of coolant in a server rack can take weeks to remediate. Cyber-physical security firms are already offering $10K+ audits to assess containment integrity before deployment.
—Dr. Elena Vasquez, CTO of ThermalTech Solutions
“DLC isn’t just about cooling—it’s about redefining the thermal envelope of data centers. The real winners will be firms that treat cooling as part of their compute architecture, not an afterthought. Legacy air-cooling shops? They’re about to get disrupted.”
Implementation Mandate: How to Stress-Test Your Cooling Stack
Before you commit to DLC, run this thermal load simulation using NVIDIA’s DGX Thermal Toolkit. Plug in your workload profile and let it model throttling risks:
# Install the NVIDIA DGX CLI tools pip install nvidia-dgx-tools # Run thermal stress test for an LLM training cluster dgx-thermal-simulate --workload "megatron-llm" --gpus 16 --batch-size 1024 --cooling-method "direct-liquid" --output "thermal_report.json" # Check for throttling events (critical if >0) jq '.throttling_events | length' thermal_report.jsonIf your report shows throttling_events > 5, your current setup is not future-proof. Time to talk to AI cooling architects.
Competitor Showdown: DLC vs. Immersion vs. Hybrid
1. Direct Liquid Cooling (Telehouse/Vertiv/NVIDIA)
- Pros: Direct silicon contact = lowest latency, highest efficiency.
- Cons: Rack redesign required; leakage risks.
- Best for: Hyperscale AI, HPC clusters.
2. Immersion Cooling (e.g., Submer)
- Pros: No moving parts; works with existing hardware.
- Cons: Fluid resistance adds 3–8% latency; corrosion risks.
- Best for: Edge AI, legacy data centers.
3. Hybrid Air-Liquid (e.g., Asetek)
- Pros: Incremental upgrade path.
- Cons: Still throttles at high loads.
- Best for: Budget-conscious SMBs.
The Bottom Line: Your Data Center’s Half-Life Is Counting Down
Telehouse’s DLC push isn’t just about keeping GPUs cool—it’s about preserving the economics of AI. Every degree saved is $10K/year in electricity for a large cluster. The firms that ignore this won’t just lose money; they’ll lose competitive relevance.

If you’re running AI workloads, your next steps are clear:
- Audit your cooling infrastructure with specialized auditors.
- Benchmark DLC vs. Your current setup using NVIDIA’s tools (see above).
- Plan your migration—because by 2027, air-cooling will be obsolete for anything beyond trivial workloads.
Disclaimer: The technical analyses and security protocols detailed in this article are for informational purposes only. Always consult with certified IT and cybersecurity professionals before altering enterprise networks or handling sensitive data.