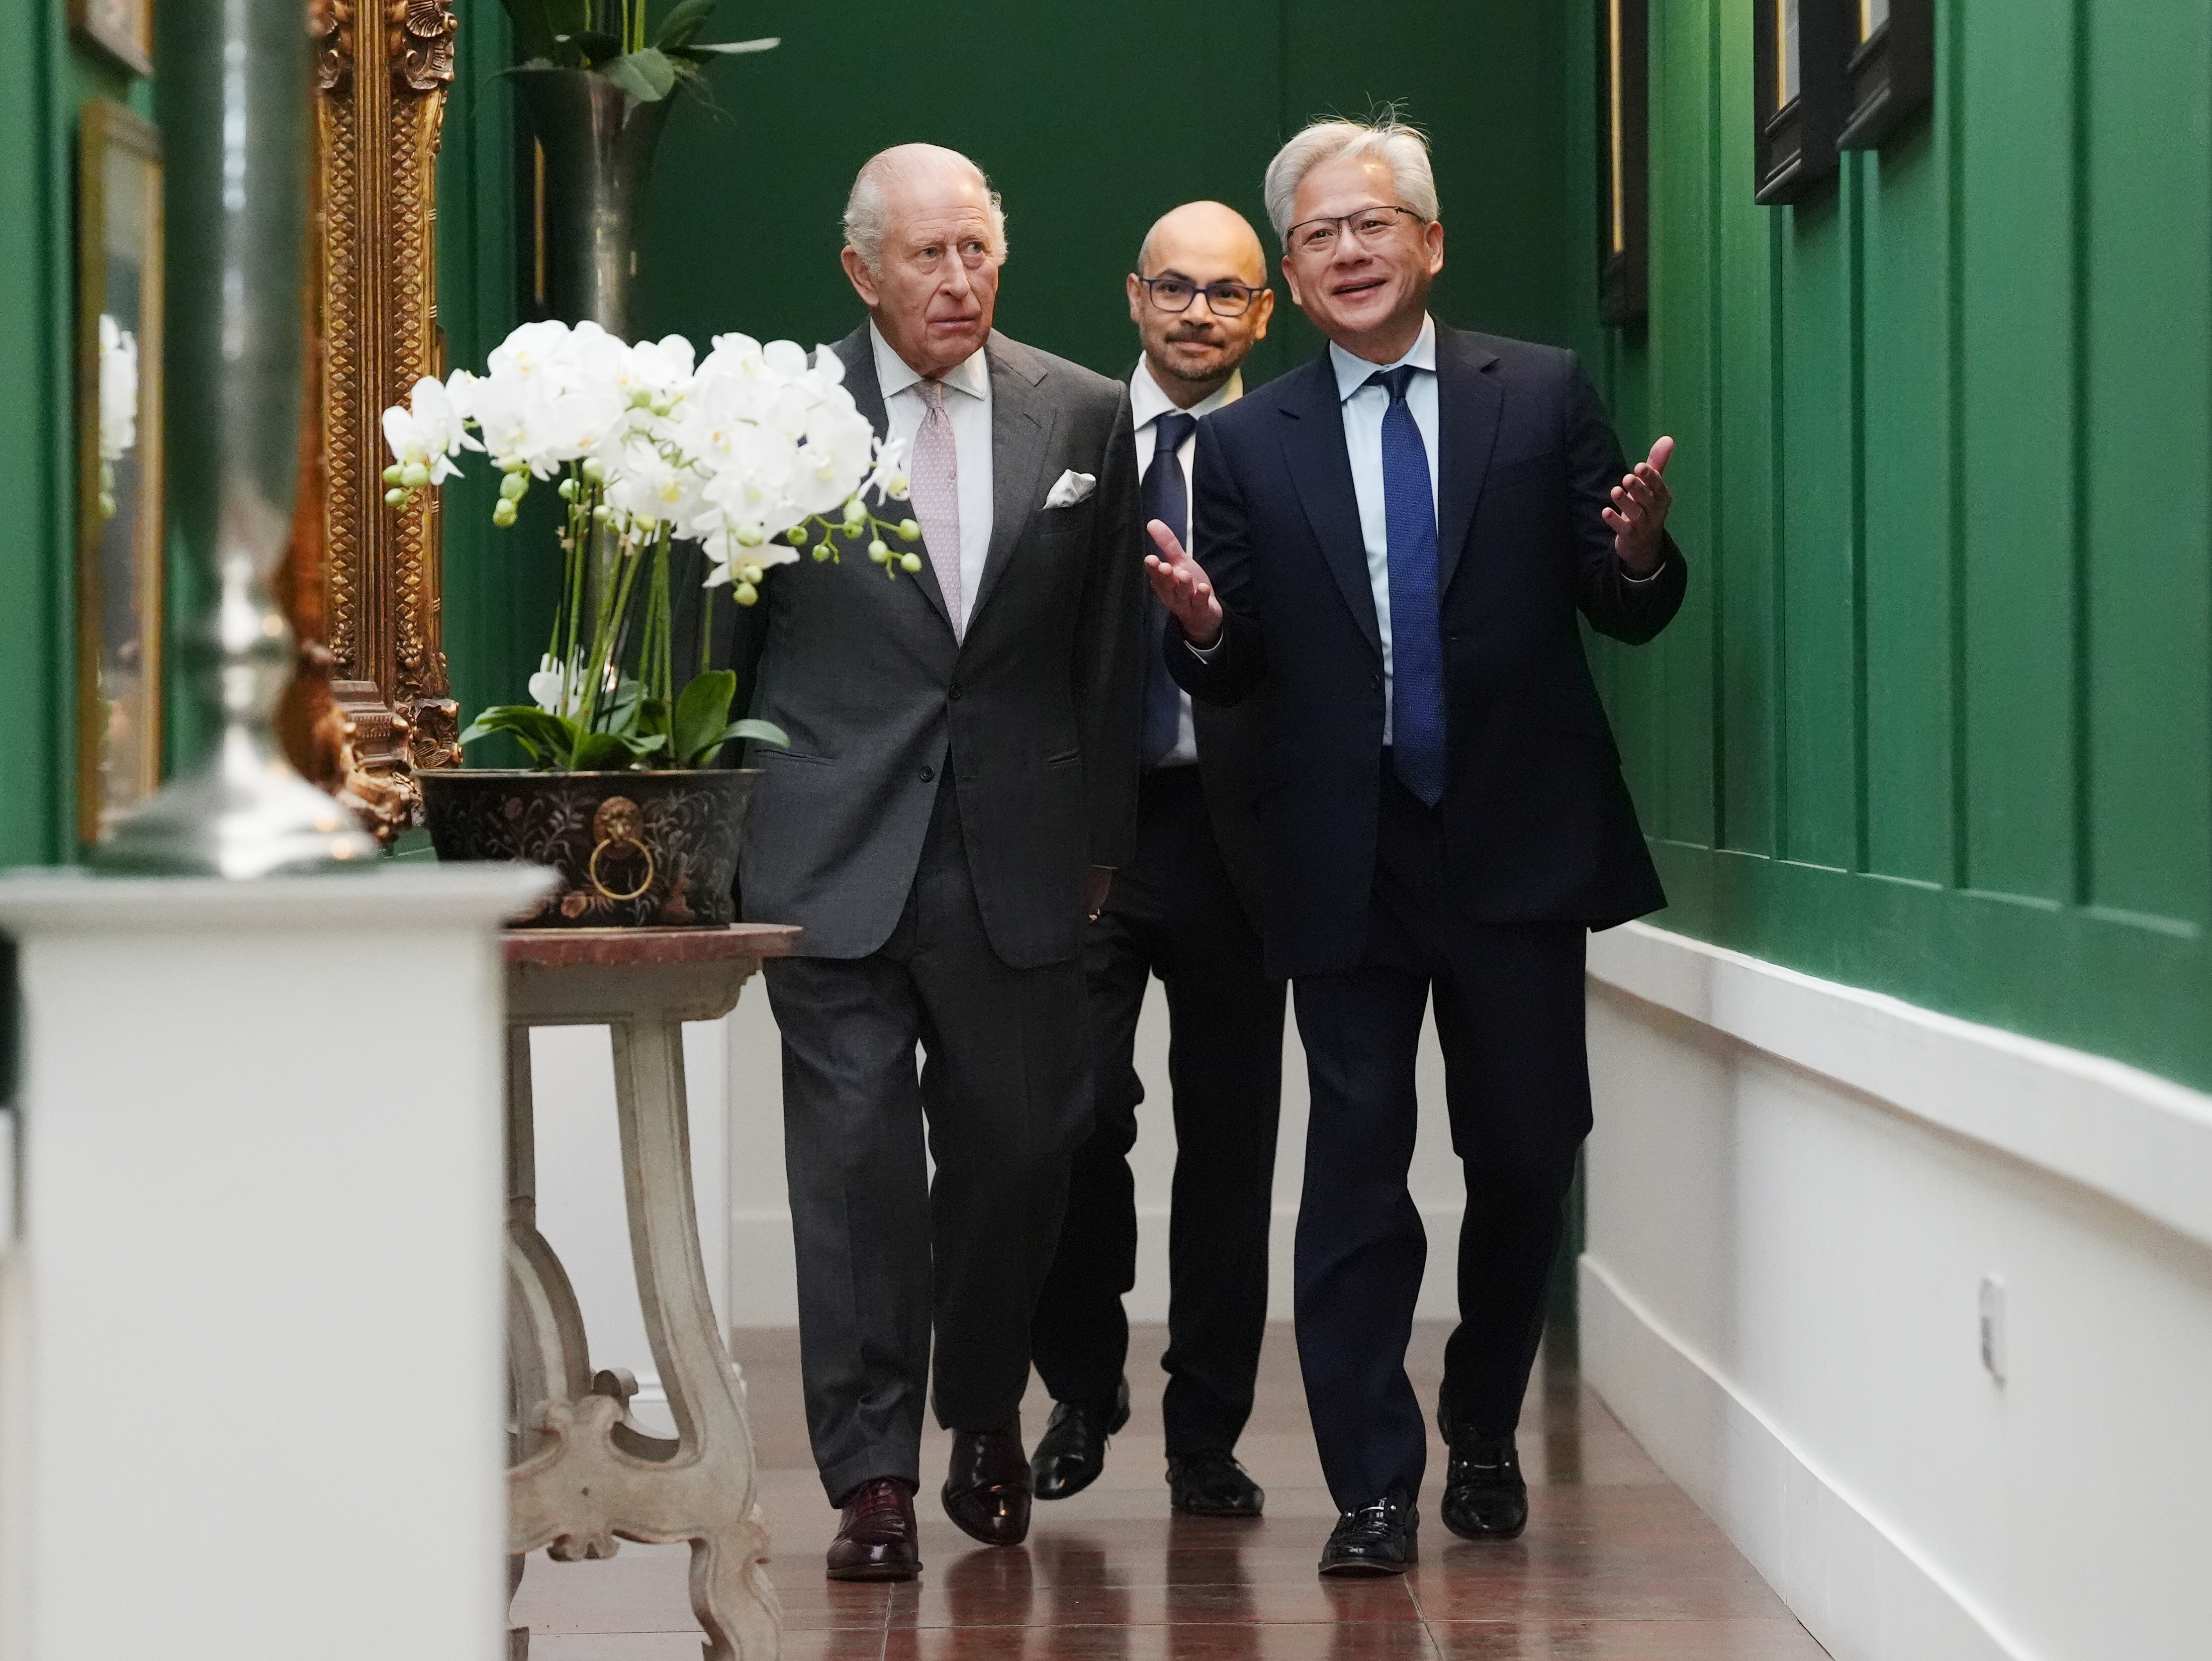
King Charles Urges Tech Leaders to Ensure Safe Artificial Intelligence Development
King Charles Meets AI Leaders: Enterprise Safety and Governance Triage
LONDON — King Charles III convened on Thursday with senior leaders from OpenAI, Anthropic, Google DeepMind, and Nvidia to address pressing safety concerns, algorithmic bias, and infrastructure vulnerabilities surrounding rapidly scaling artificial intelligence systems.
The Tech TL;DR: Enterprise Impact
- High-Level Engagement: King Charles III met directly with executives from OpenAI, Anthropic, Google DeepMind, and Nvidia in London to evaluate safety guardrails for scaling LLM deployments.
- Operational Friction: Enterprises face immediate compliance burdens as global regulators demand verifiable SOC 2 compliance, robust end-to-end encryption, and rigorous containerization standards for AI workloads.
- Actionable Triage: IT departments must bypass vendor hype and audit existing Kubernetes clusters, API rate limits, and zero-day exposure profiles immediately.
Architectural Bottlenecks and Safety Compliance in Production
As enterprise adoption scales from proof-of-concept sandboxes into mission-critical production pipelines, the friction between raw compute velocity and rigorous safety protocols becomes painfully obvious. High-performance accelerators from Nvidia push massive floating-point operations per second (FLOPs), but managing inference latency while maintaining strict data sovereignty remains a monumental engineering headache. Organizations deploying foundational models from OpenAI or Anthropic across distributed microservices must lock down their network boundaries.
According to recent industry telemetry and infrastructure benchmarks, unmitigated API calls and poorly configured container environments invite severe lateral movement vectors. Security teams cannot rely on perimeter defenses alone; zero-trust architecture and automated vulnerability scanning are non-negotiable requirements. When integrating advanced natural language processing APIs, developers face strict payload constraints and token rate limits that break legacy middleware if not properly load-balanced.
Deploying Secure AI Pipelines: A Practical Configuration
For systems engineers and backend developers tasked with deploying containerized AI inference engines locally or within private cloud environments, rigorous configuration is essential to mitigate data leakage. Below is a foundational Docker Compose snippet designed to isolate an inference container, enforcing strict resource limits and restricting outbound network telemetry.
version: '3.8'
services:
  llm-inference:
    image: nvcr.io/nvidia/k8s/cuda-sample:vectoradd-cuda10.2
    container_name: secure_llm_runtime
    restart: unless-stopped
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: 1
              capabilities: [gpu]
    environment:
      - NVIDIA_VISIBLE_DEVICES=0
      - ALLOW_REMOTE_TELEMETRY=false
    networks:
      - isolated_net
    security_opt:
      - no-new-privileges:true

networks:
    isolated_net:
        internal: true
Securing runtime environments requires specialized intervention. For organizations struggling to harden their Kubernetes deployments against adversarial prompt injection and model extraction attacks, engaging vetted open-source security tooling or collaborating with specialized enterprise infrastructure consultants provides the necessary defensive depth. Enterprise IT teams should immediately audit their continuous integration and continuous deployment (CI/CD) pipelines to prevent accidental credential exposure in model weights.
Evaluating Model Infrastructure and Threat Surfaces
Examining the deployment stack reveals stark contrasts in how different accelerators handle concurrent enterprise workloads. While cloud-native APIs offer rapid time-to-market, they introduce third-party data governance dependencies that violate strict financial and healthcare regulatory frameworks.

Engineering leads facing infrastructure bottlenecks or compliance audits must prioritize rigorous endpoint testing. Organizations lacking internal capacity should consult with vetted software development agencies to refactor legacy monoliths into scalable, containerized architectures capable of handling heavy AI inference loads securely.